

Nicola Romanò @nicolaromano@social.cleverlibre.org
Senior lecturer at ZJE and Edinburgh university.
I teach #imageanalysis & #dataanalysis with #RStats & #python. I study #heterogeneity in #pituitary (and other) cells.
Joined Oct 2022
Is there any one familiar with analysis of #nanopore #longreads ?
I'm having some bizarre issues when using #minimap2 to align them and I'm almost out of ideas of what to try next...
Here's an explanation of my issue
Nicola Romanò
boosted

Wow, this paper on #scRNAseq and differential expression methods is an eye opener. https://www.nature.com/articles/s41467-021-25960-2
Nice overview of methods and relatively easy to understand explanation of what is wrong with certain, especially single-cell-specific, methods.
Of great help in my own scRNA-seq efforts. Should probably have read this earlier. Now, back to R I go. 😅
@scullingmonkey I was not thinking about the absolute numbers, rather the fact that they're not keeping an account of the numbers. Even if legal (it wouldn't be in the UK or in Europe) it's definitely bad scientific practice
@scullingmonkey "the company does not keep precise records on the number of animals tested". I am not familiar with US law... but is that even legal?
@CharlesO wondering if this is a scam to get you to pay publishing fees? Is this person an actual professor at that uni?
Nicola Romanò
boosted

As a blind individual, I have to say that #Caturday on #Mastodon is far far more enjoyable then at #Twitter, where the vast majority of cat photos are not described.
It is also been fascinating for me to hear descriptions written by those who sent the image, immediately followed by Apple image recognition’s attempts to describe the same image. Only rarely does that add anything to the ALT, & often directly contradicts it.
There is no auto magical solution to image description. It is something best done by a human, for only that human can explain the “why” of the image: the reason that image was chosen to speak so eloquently without words for those who can see it. ALT allows you to provide those words.
Nicola Romanò
boosted

Pride in history can be detrimental to progress. It can make people delusional that they’re special relating to times they didn’t exist in. The reality of those times is often translated to them as one-sided stories where they imagine themselves to be the heroes. They get stuck.
Nicola Romanò
boosted

"More than our rank".
This is an initiative that every university would do well to join, regardless of its ranking.
Indeed, each institution, for various reasons, many of which are its own, is worth much more than the rank assigned to it by a limited, indigent and ideologically connoted system of indicators.
https://inorms.net/more-than-our-rank/
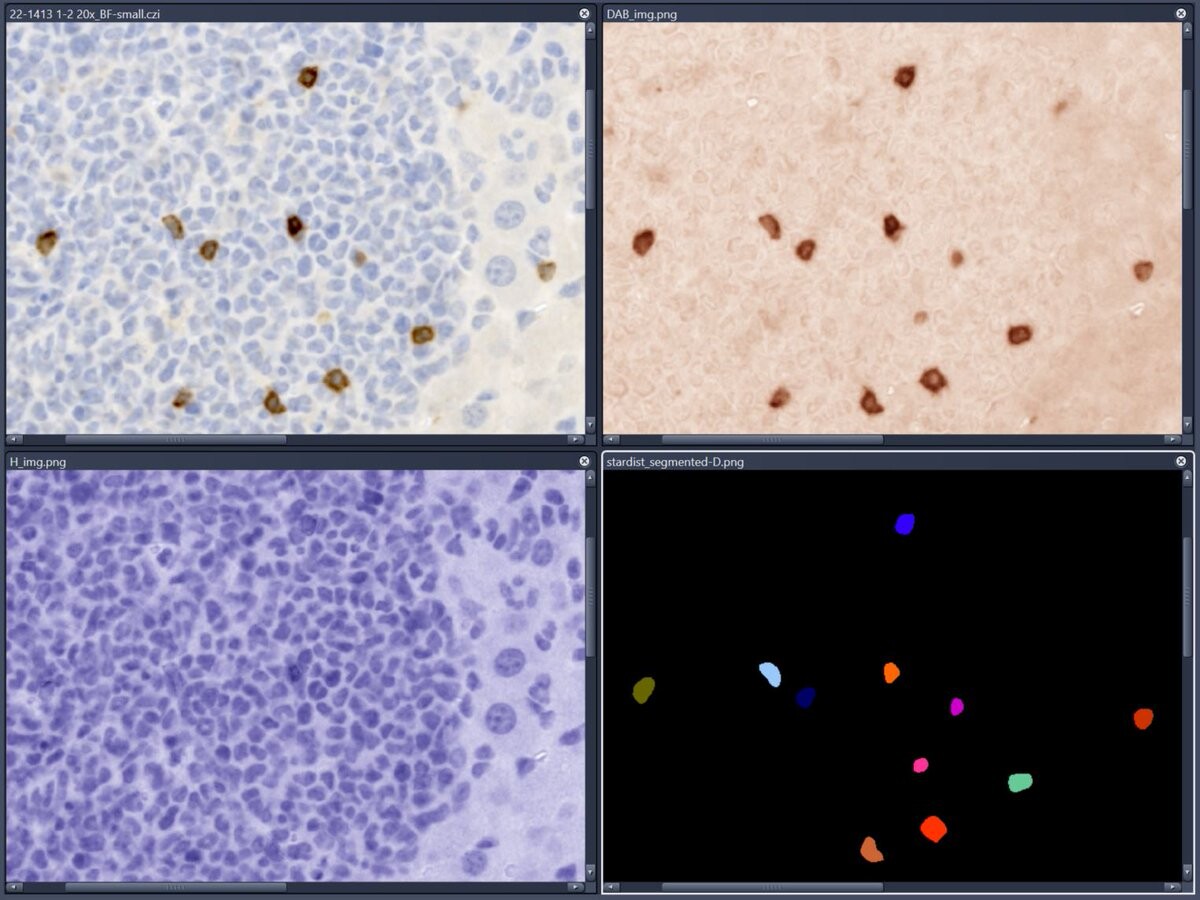
@joshburnett @digitalsreeni That looks like a thresholded version of the top right, followed by detection of connected areas of pixels. scikit-image is a great tool to use for these things.
Nicola Romanò
boosted

It only takes a few lines of #python code to gain insights from scientific images.
They are just a click away if you are not into coding - ask me about it.
#deeplearning #bioimageanalysis #microscopy
@DavidKnuffke That is cool, but I would not rely 100% on it; indeed, I tried on a few outputs, and while some are detected as <1% real, others are considered >90% real. I haven't, however, found a piece of text written by a student that was classified as AI-generated (however, I have only tried a few).
I would be extremely careful about relying on such a tool as "proof" of academic misconduct.
Most of all, I think that discussing these tools with students is extremely important.
@gerard_mazza@kolektiva.social Only partially agree. I had ChatGPT give answers to questions that required some critical understanding of fairly complex experimental design, which is very much a real-life skill that students need to learn in my field...
Nicola Romanò
boosted


Why? I really started believing in federated platforms (again). That’s what the internet was and should be. I must take the sacrifice for this belief, despite loving the Twitter community.
Nicola Romanò
boosted

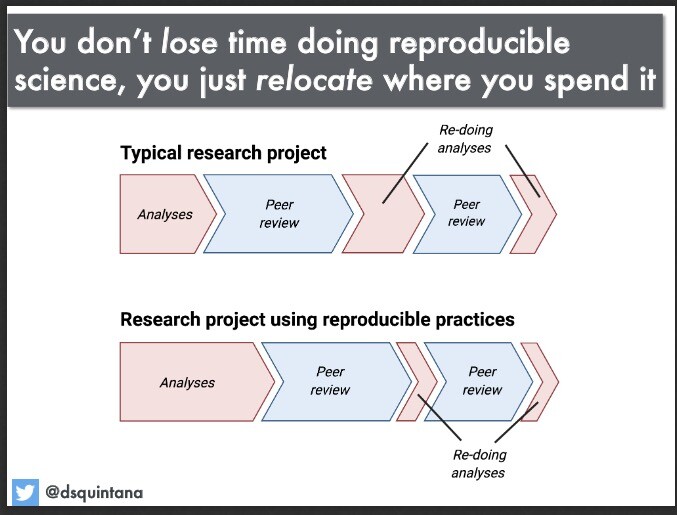
The slides for my recent intro to open science (OS) talk, including 5 things about OS that everyone should know
➡️ https://osf.io/zy2pc ⬅️
1. OS practices accelerate scientific discovery
2. Adopting OS practices can make you a more competitive job/grant applicant
3. Data sharing is on a continuum (it doesn’t have to be either fully open or fully closed)
4. Take it one step at a time, you don’t have to learn every skill at once
5. Your future self will thank you for adopting OS practices
Nicola Romanò
boosted
@nathanhuneke @JessButler @rlmcelreath https://royalsocietypublishing.org/doi/10.1098/rspb.2022.1113
This is an interesting analysis of the topic
Nicola Romanò
boosted

🔖 Statistical code in a high-impact medical journal
A journal started asking authors to submit code with their manuscripts. They then analysed the next 314 papers accepted
87% denied using code, even when publishing substantial statistical analysis
10% used code but refused to share it with the journal
For the few that provided code, none scored even moderately on basic quality criteria
Assel & Vickers
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC6705117/
#MedMastodon
#OpenScience
#ResearchWaste
#doi:10.7326/M17-2863
Nicola Romanò
boosted

Thanks to a toot from @DavidKnuffke that I saw this morning, I tried another #AI tool - Elicit https://elicit.org/
"This workflow tries to answer your research question with information from published papers."
My example is shown here with my initial question in the red box. Wow.
#EdTech #EduTooter #Education #GoogleEDU
Nicola Romanò
boosted


Just making sure that the Mastodon #rstats community is aware of the {dadjoke}  package. And if you need it, add this to your .Rprofile for a dadjoke on startup:
# Dadjoke on start up
if (interactive())
dadjokeapi::groan(sting = FALSE)
Nicola Romanò
boosted
🔖 Do cancer researchers make their data and code available?
306 cancer studies:
16% shared data
4% shared analysis code
1% of data were FAIR (posted to a recognised repository, in a non-proprietary format, with an identifier and a license)
Cancer research transparency was this bad despite many journals having policies mandating openness.
Daniel Hamilton et al
https://bmcmedicine.biomedcentral.com/articles/10.1186/s12916-022-02644-2
#MedMastodon
#OpenScience
#ResearchIntegrity
#ResearchWaste
#doi:10.1186/s12916-022-02644-2
Senior lecturer at ZJE and Edinburgh university.
I teach #imageanalysis & #dataanalysis with #RStats & #python. I study #heterogeneity in #pituitary (and other) cells.
Joined Oct 2022
