

Ryuichi @ryuichi@social.cleverlibre.org
Discover a new world of digital imagery produced through the advanced machine learning algorithms we utilize. Follow our account to witness stunning visuals generated through the latest in technology and computer science.
Joined Apr 2023
Ryuichi
boosted

Ryuichi
boosted
Lora, called flat and flat2, intentionally learns low-detail images, which apparently improves the detail of generated images when Lora strength is specified with a negative value. For example, it can be specified as <lora:flat2:-1>. It's a interesting idea.
Ryuichi
boosted

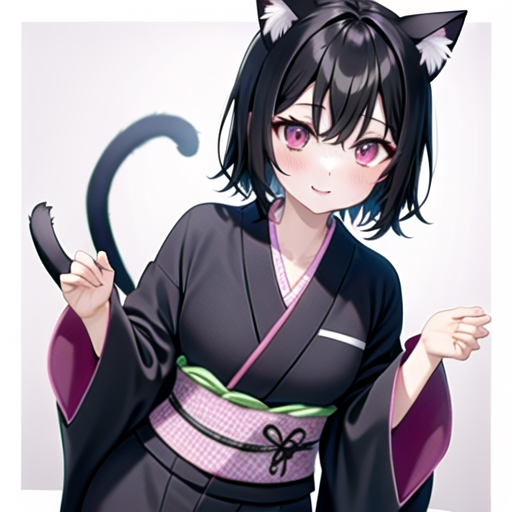
"I've seen a lot of people in kimonos lately. I decided to try one on. How does it look?"
"最近、着物姿の人をよく見かけるようになった。試着してみることにしました。どんな感じなんだろう?"
#aiart #StableDiffusion #AIイラスト #catgirls
Ryuichi
boosted
Ryuichi
boosted
Ryuichi
boosted




@ryuichi@qoto.org https://comfyanonymous.github.io/ComfyUI_examples/faq/ explains it better then i can.
The main benefit for me is control over upscale, instead of doing one big hiresfix step, I have a custom workflow that's a couple of small upscales instead of one big. The prompting is mostly the same, I never really used weights that much so the different behaviour isn't really an issue. Heres an example of my workflow, its somewhat overloaded, but i have plenty of flexibility with just moving couple of outputs around.


I tried to use another stablediffusion user interface called "ComfyUi", it's node based, but for some reason all the images came out very ugly, nothing like the kind of images i get from Auomatic WebUI and i was using the exact same model, i don't know what happens.
Discover a new world of digital imagery produced through the advanced machine learning algorithms we utilize. Follow our account to witness stunning visuals generated through the latest in technology and computer science.
Joined Apr 2023
