
Kragen Javier Sitaker @xentrac@social.cleverlibre.org
- country
- Argentina
The only AI I have ever used to write my posts is my cellphone keyboard's autocomplete. I even turned off autocorrect. But I write a lot about things I used AI to make, so you might not want to follow me if that is going to upset you. I understand. I'm terrified myself.
I know an enormous number of things, some of which are even true.
I'm not interested in fighting. If you're here to fight, I will probably not follow you or respond to you. Disagreement does not constitute a personal attack. I'm interested to hear your point of view. If it's about an objective matter, I want to be right so much that I will change my mind if I'm wrong. Usually, I hope.
Joined Sep 2023
I think more people should know about #reflinks, which I learned about from @leah years ago.
(100% human-written prose. I use em dashes and bulleted lists because they make the prose clearer. Also, I like them.)
Immutable copy-on-write snapshots of things are kind of a superpower for computer systems design. (FP folks call this "persistence.") An awfully large fraction of computers' time is spent copying things from one place to another to keep them from changing. In a lot of cases, this is unnecessary, because they weren't actually going to change in the first place, but it can be hard to be sure in advance. If you have some kind of system that will copy *only* the things that get modified — or the *parts* of those things that get modified — it will often be much more efficient. So, in Linux, we use this a lot in copy-on-write memory mappings of files, process memory following a fork(), and things like that. rsync has a --link-dest option that allows multiple backups to share space while being just as convenient to use as regular non-incremental backups. There are many other examples.
Some OSes and some filesystems support making a copy-on-write "copy" of a file, sharing the space between the original file and the "copy" until and unless one of them change. This feature is usually called "reflinks" after the Solaris system call that supports it.
In particular:
On #Linux:
- Bcachefs,
- btrfs,
- XFS, and
- OCFS2.
But *not* OpenZFS.
On #FreeBSD, neither OpenZFS nor #ZFS.
On Solaris, ZFS (with `cp -z`).
On MacOS, APFS (which Apple is switching to; with `cp -c` or the `clonefile` system call)
And, on Microsoft Windows, NTFS and its DUPLICATE_EXTENTS_TO_FILE.
These are from Daniel Aleksandersen's 02020 blog post https://www.ctrl.blog/entry/file-cloning/. I don't think anything has changed on that front since then, which is sad, if true.
Kragen Javier Sitaker
boosted

@maya @OmegaPolice @britter Most banking apps work on GrapheneOS but many have memory corruption bugs and incorrect anti-tampering code requiring our per-app exploit protection compatibility mode toggle.
Around 10% of banking apps are unavailable due to banning using a non-Google-approved OS. Around a dozen banking apps began specifically permitting GrapheneOS in addition to a Google-approved OS which is growing.
There's a good list based on ongoing user reports:
https://privsec.dev/posts/android/banking-applications-compatibility-with-grapheneos/
Kragen Javier Sitaker
boosted
I'm pleased to find that I have a Mathstodon account now. I'm trying it out, and I'm pleased with its \(\LaTeX\) support.
This toot is a test of \(\LaTeX\) rendering support.
Kragen Javier Sitaker
boosted

@whitequark @farseen @jackdaniel @snowfox
I think the words 'fun' and 'enjoyment' are misleading here. I think I would prefer 'emotionally satisfying' or 'rewarding' (in the non-financial sense). I work on open source things because I want them to exist. When other people find that they also solve problems for them and they don't have to start from scratch, I find that satisfying. That's largely decoupled from the fun of tinkering or the joy of creation, which is something that comes and goes depending on the stage of a project and my frame of mind.
Kragen Javier Sitaker
boosted
Since I'm on Via Rail, and the Via Rail connectivity situation is... typical, does anyone On Here have a preferred approach to local/remote sync that's robust in the face of serious network sporadicity?
I could gin something together with rsync but I'm hoping there's something out there prebuilt; that feels like zero lag local editing, that stores deltas and pushes them to remote in some reliable way as soon as the far end reappears.
It feels like a database-reliability shaped problem.
Kragen Javier Sitaker
boosted
I want to finish with some thoughts about software quality.
The vulnerabilities above were, as far as I know, in human-written code. Some or all were found with the aid of LLMs.
If, as some believe, and, yeah, I think there is mounting evidence for this, a lot of future systems are built mostly by LLMs, what do vulnerabilities look like in that world? Is this software more secure? Or less?
I see five reasons to despair and two causes for hope.
The first reason to despair is that the large LLM-built systems that I've spent any time looking at, and which I've seen others' analysis of, are security nightmares. They are full of duplicated, but inconsistent, security checks. They have what you might call a security architecture, but then data flows through them in ways that means that just about anything can happen anyway. They have ad-hoc conditions and arbitrary limits. They are awful.
But wait: won't better models write more secure code? Well, here are my next two reasons to despair.
In order to produce secure code, you have to care about producing secure code, and you have to be able to tell how secure the code is. Yeah, people screw this up. In fact, they *usually* screw it up. But: I think that both of these factors are *often* (not always!) lacking in LLM-generated projects. A major use of LLMs is for people to do things that they are not, themselves, very good at. Makes sense! But if you (not you personally, of course, some other "you") don't have expertise in understanding the security of web applications, well, you're not really going to be able to tell whether the thing the LLM generates for you is very secure, are you? Additionally, our current moment has shifted the balance towards caring about "just building cool new stuff", and away from caring about its security. Again: not new, that's a pretty normal instinct. But, as the value of the code itself gets driven to zero in favor of the value of the product, the value of security is getting driven in the same direction.
Okay, maybe you don't care about the security of the code, and wouldn't be able to tell how secure it was anyway, but surely the LLM "cares" and can tell, right? I don't think so. A major strategy used to improve the quality of code that comes from LLMs is extensive testing. People hate writing tests, but matrix math doesn't hate anything, so you can get it to churn out huge amounts of test cases. Maybe some of them are even good! Then you can follow an iterative improvement process, where the LLM produces code, it gets tested against various things, if it fails, it gets improved until it passes. But security is not so testable. Knowing that something is secure means proving that some undesirable thing *cannot* happen. You can't "prove" something like that through testing, without testing every possible execution (as well as being able to precisely define and identify "what shouldn't happen"!) (I know! I know! Formal methods! I'll get to that in a minute!) Plus, most security vulnerabilities these days involve things like complex orderings in concurrent code, resource exhaustion of various types, complex chains that corrupt values in one place and make use of that corruption much later in other code paths, re-use of the application's own code as "gadgets" to execute attack logic - the kind of stuff that is just a nightmare to test. We're not talking your basic unit test here where you check to see if the code URL-encode values in a string. Tools like fuzz testing, or LLM-based vulnerability search are great auditing tools. But they are slow, expensive, and not really part of iterative development loops. So, no. I don't think testing by agentic loops or semi-antagonistic LLM "teams" is going to make up for lack of careful human oversight.
I don't dispute that LLM-written code is getting, and will continue to get, better. I don't dispute that a person who cares about producing secure code and is capable of understanding its security properties *can* use LLMs to generate code that is as, or maybe even more, secure than human-written code. But I do not believe that the major things driving improvements in LLM code are going to drive us to more secure code.
Fourth, products that, themselves, contain an LLM that is hooked up to "tools" that can interact with something other than just text (coding agents, personal assistants, etc.) have an extremely strange security posture. Most software products are built to protect themselves, and hopefully you, from "external" threats: network attacks, malicious files, that kind of things. But products with an LLM in them have to be built to protect *you* and *the external world* from the *product*. If the product has access to your medial history, and email, then you have to consider the fact that the product might email your medical history to Mark Zuckerberg. Bizarre. Based on what I've seen of coding harnesses and personal agents, we are exceptionally bad, so far, at adapting to this threat model.
Fifth, LLMs generate a lot of code. A LOT of code. They are not limited by exhaustion, boredom, or frustration. They are, to a degree, limited by time, but this is why people use multiple agents to ramp up the code output. The more code, the more it tends to contain vulnerabilities. We've known this forever. Yeah, of course, you can take precautions against it. But that doesn't change the basic math. Vulnerabilities in human code are limited, in part, by the fact that humans only write so much code. If you believe in a world (which, to an extent, we are already in) where LLMs churn out far more code than humans ever did, then you've removed one of the caps we had on how many vulnerabilities were getting created.
Two reasons to be optimistic, though:
First, there's formal methods. These are ways that you *do* get to prove properties - including security properties - about code. Far more powerful than testing it to death. Think mathematical proof of additive identity, instead of exhaustively testing that every integer, when you add zero to it, is still the same. This has historically been a hell of a lot of work, but some parts of the proofs have gotten more mechanized, and people are trying to get LLMs to do some of the other tedious work that has previously made this infeasible for large complex systems. This may work out well. I'll rain on this parade a *little* though, because you still have the problem that you need to be sure that the formal, math-like properties you're proving about the software (a) correspond to the informal things you care about ("does not send my medical history to Mark Zuckerberg"), and (b) are comprehensive. I don't see these being particularly compatible with *most* vibe coding.
Finally, there's a significant chance that the current euphoria (in some quarters, anyway) for churning out huge quantities of code, just because we can, might cool off. This would reduce the "too much code" problem, and may reduce the amount of code generated by people who do not and cannot care about its security. There are, I would propose, limits to how much software we can realistically use - right now, there is plenty of novelty to be grabbed, but eventually we'll reach a sort of saturation again where, yeah, we do still produce a lot of new software, but it's limited by how much software anyone actually *wants*. Perhaps, once Candy Crush *does* start emailing your medical history to Mark Zuckerberg because an ad asked nicely, we might start caring a bit about security, too.
(Okay, I realize, that's pretty much what was going on BEFORE LLMs, and we didn't care then, either, sorry for failing to end on an optimistic note.)
Kragen Javier Sitaker
boosted

@jonmsterling I’d approach this by teaching the underlying structural observations behind cartesian products of rings, but keeping things concrete by avoiding the abstraction layers of defining what a ring is
for example, the extended Euclidean algorithm is best understood as “for fixed a and b, numbers expressible as ax + by form an ideal, and the algorithm functions by maintaining constructive witnesses for belonging to this ideal”, but you can explain this without defining what rings or ideals are
or, Fermat’s little theorem and Euler’s generalization of it are best understood in terms of “the cosets of a group partition the group, and the cosets are equinumerous”, but instead of defining groups or cosets, you can draw the graph whose vertices are remainders, with edges defined by the “multiplying by some constant a” map, and then observe that it forms these circular bracelets that are all the same size…
I haven’t thought about how to teach the CRT in particular, but I’d expect that similar ideas can be found here as well. I suppose it is in a way similar to Conor’s approach of teaching categorical structure without the use of categorical language…
Kragen Javier Sitaker
boosted

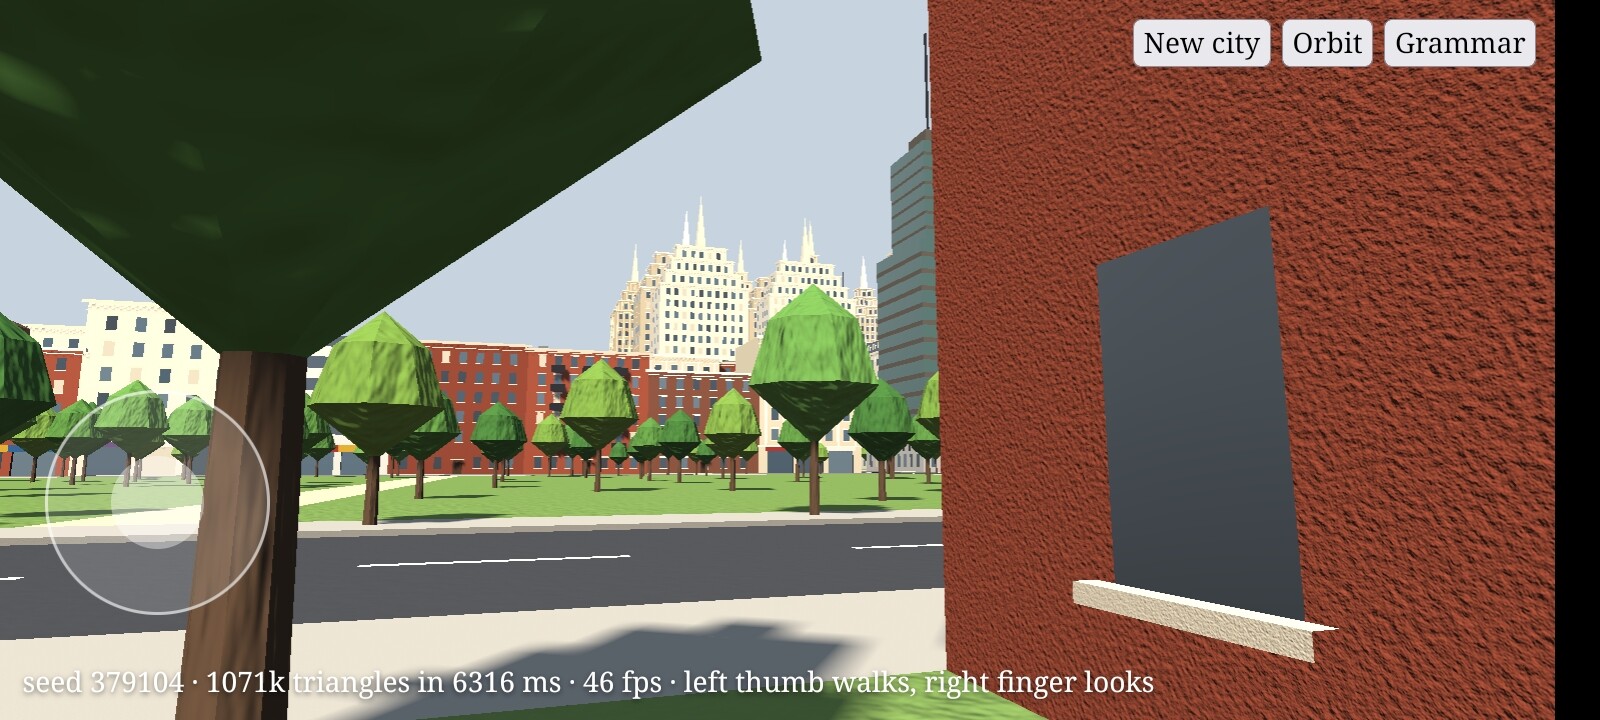
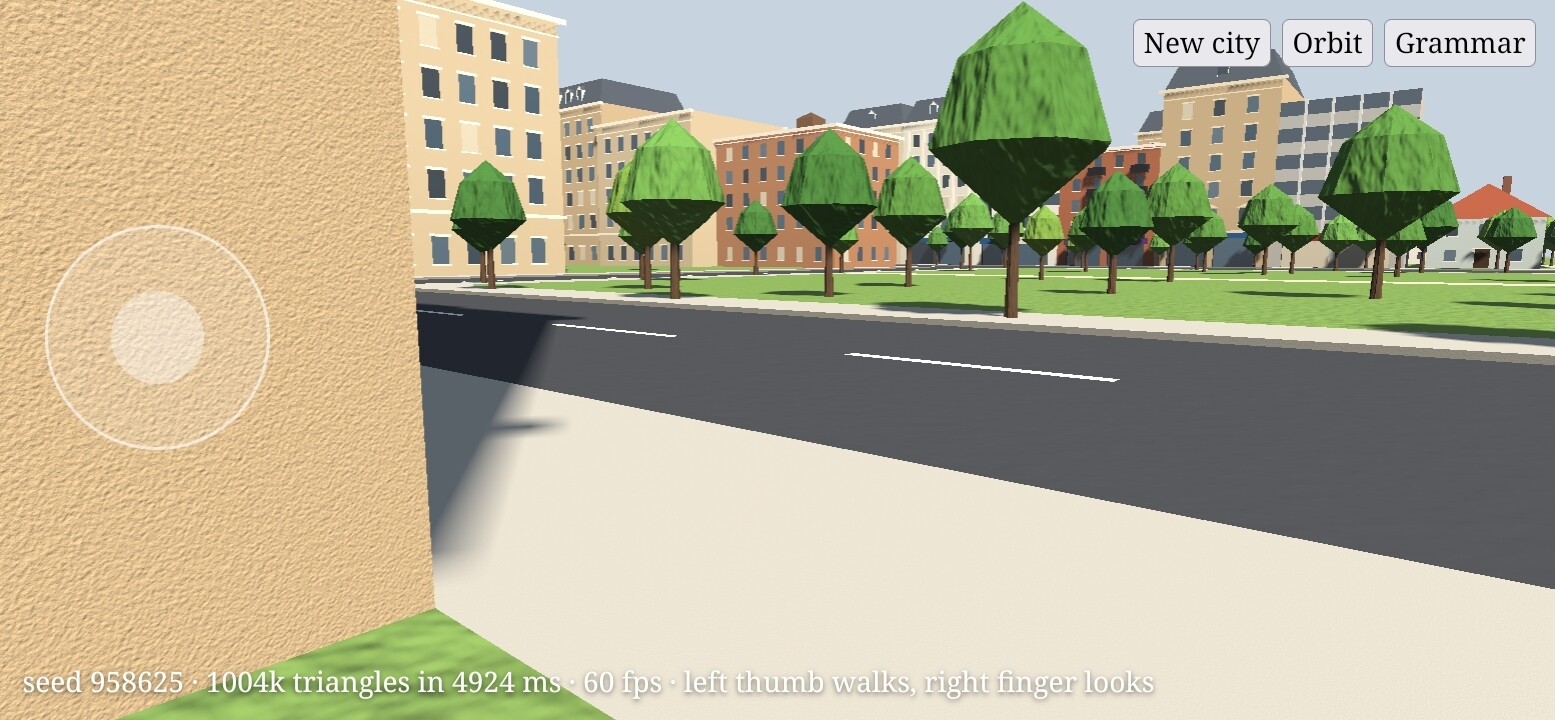
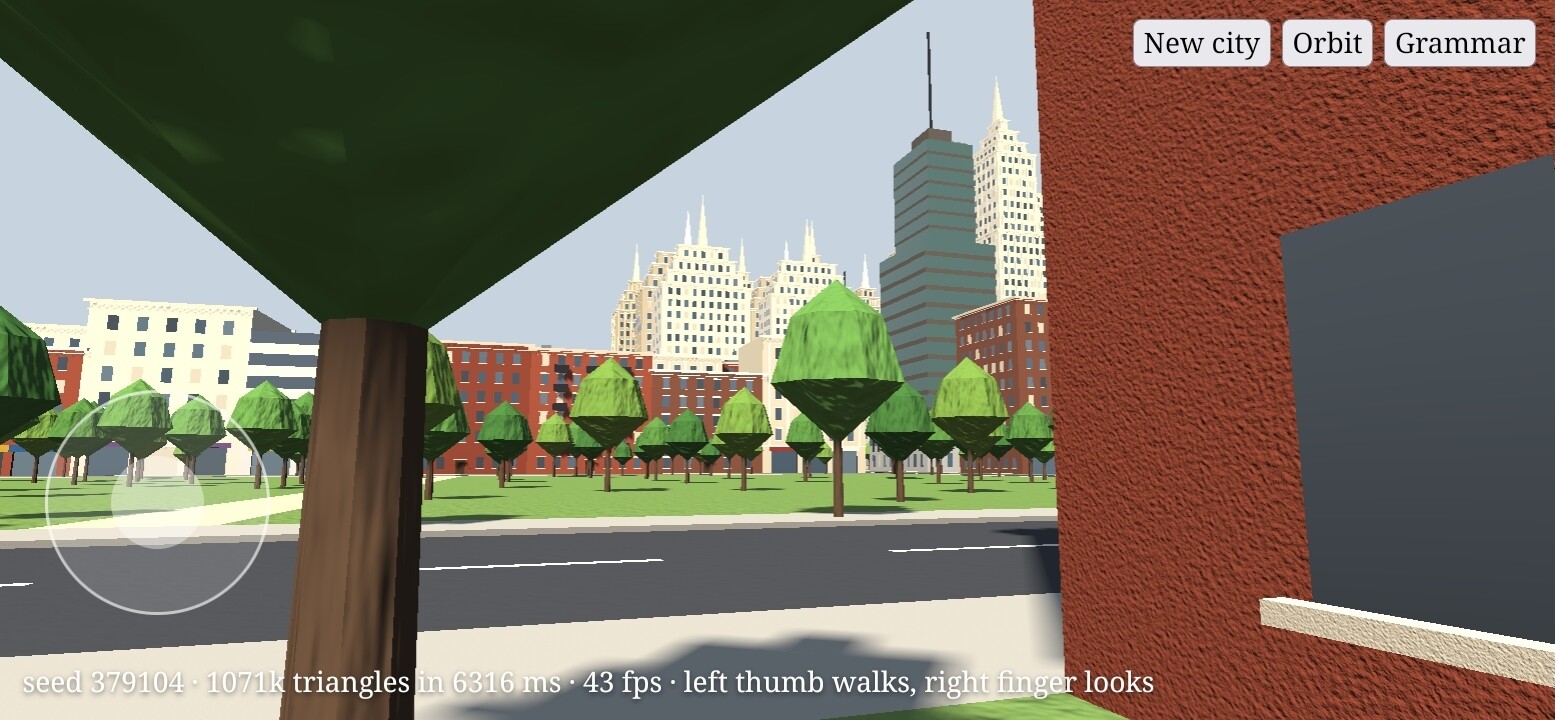
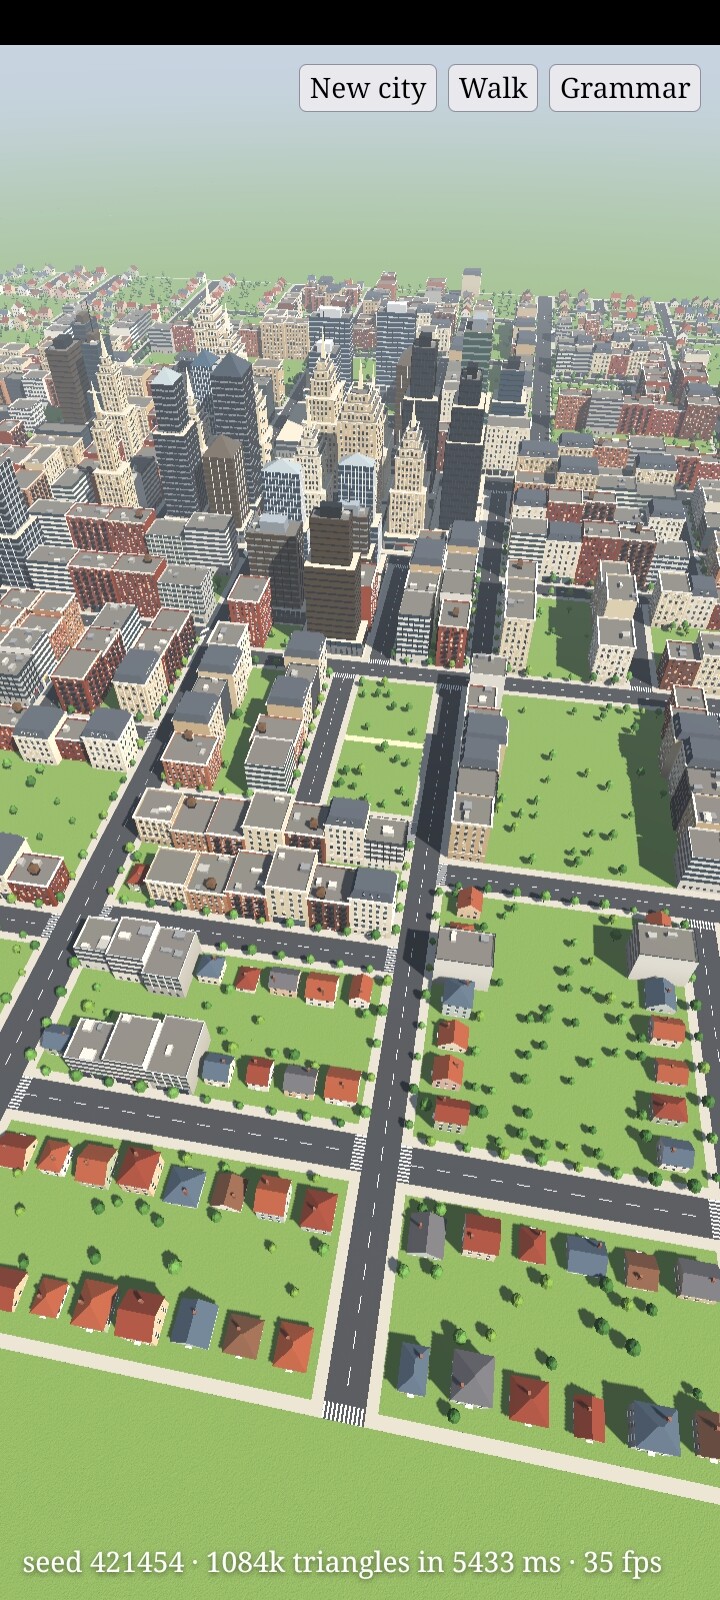
I elicited this stochastic city generator from Claude a few weeks ago, Opus 5.0 I think. You can edit the CGA shape grammar (expressed in JS rather than CityEngine's shape grammar language) that generates the city and walk around it in your browser with WebGL.
I've been keeping a low profile for the last few years, but I'm happy to be back on the Fediverse. I'm still in Argentina, still shamelessly liberal, still committed to free software and free society.
Kragen Javier Sitaker
boosted

not to think out loud but i have been wondering what form another web could take, in response to the constant ddos
one way is a more fidonet approach, interlinked groups and manual peering. as a means of somewhwat opting out and moderating crawlers
but well, sometimes it feels like the right answer is to go all in on more content-addressable, bitorrent like approaches, essentially making scrapers earn content through contributing bandwidth
but yeah that means everythings way more scrapable
- country
- Argentina
The only AI I have ever used to write my posts is my cellphone keyboard's autocomplete. I even turned off autocorrect. But I write a lot about things I used AI to make, so you might not want to follow me if that is going to upset you. I understand. I'm terrified myself.
I know an enormous number of things, some of which are even true.
I'm not interested in fighting. If you're here to fight, I will probably not follow you or respond to you. Disagreement does not constitute a personal attack. I'm interested to hear your point of view. If it's about an objective matter, I want to be right so much that I will change my mind if I'm wrong. Usually, I hope.
Joined Sep 2023
