

Nicola Romanò @nicolaromano@social.cleverlibre.org
Senior lecturer at ZJE and Edinburgh university.
I teach #imageanalysis & #dataanalysis with #RStats & #python. I study #heterogeneity in #pituitary (and other) cells.
Joined Oct 2022
Nicola Romanò
boosted

Oh, man. This comic — from 1993 — could NOT be more relevant today. As usual, Bill Watterson hits it out of the park.
Nicola Romanò
boosted

Random first trial post: today, March 14th, is the 29th anniversary of the Linux 1.0 announcement.
Of course, there are other arguably more important dates in Linux history, but this is one of them.
Nicola Romanò
boosted

RT @Apeer_micro
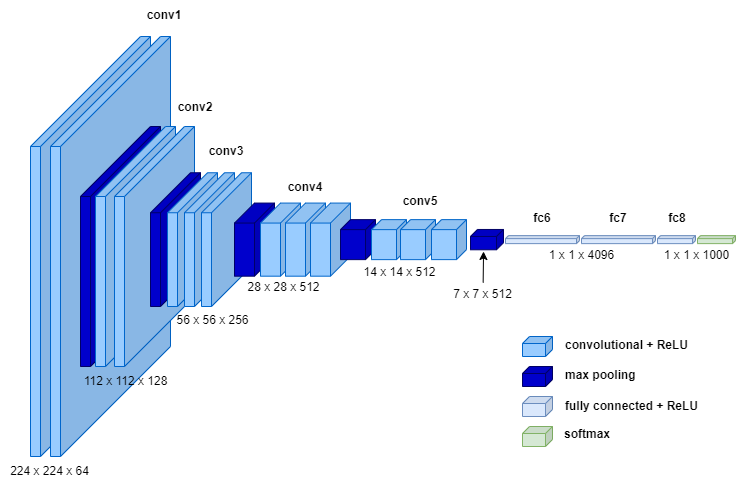
Learn how feature learning works in CNNs
Want to know the technique that gives #DeepLearning an edge over #MachineLearning?
Read our blog to find out.
https://hubs.la/Q01F6Nvp0
Nicola Romanò
boosted


Ready to give Fedora Linux 38 a test? The beta release is here!
#Fedora #Linux #OpenSource
Learn more: https://fedoramagazine.org/announcing-fedora-38-beta/
Just finished reading this very interesting #review about #analysis of #scRNAseq data from different #species.
"Cross-Species Analysis of Single-Cell Transcriptomic Data" - Schafer - Front. Cell Dev. Biol 2019
https://www.frontiersin.org/articles/10.3389/fcell.2019.00175/full#B5
Nicola Romanò
boosted

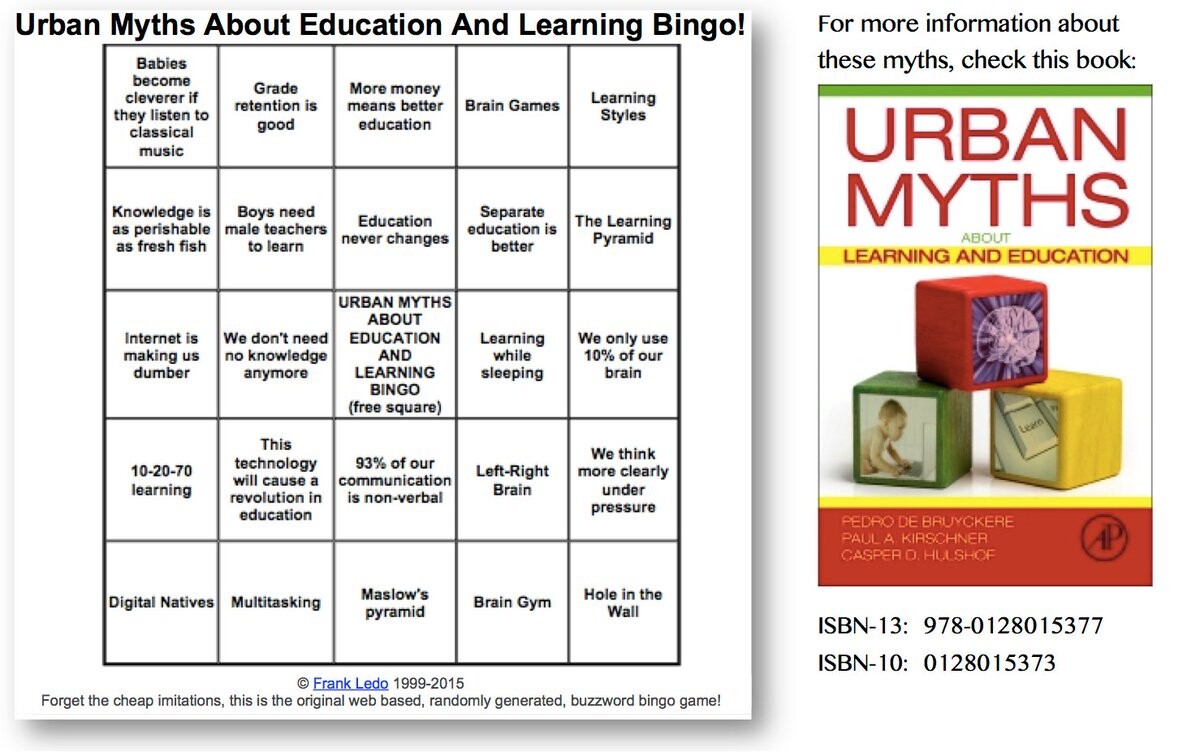
I hoped this bingo card would have become outdated because people would have started to know that these are myths. Sadly, this isn't the case.
Nicola Romanò
boosted

""The honors thesis must be a *single author* document written by the student."
Rules like this represent an antiquated approach to #science and harm the undergraduate researchers involved by teaching them that science is done by isolated individuals & that it's appropriate to not credit all contributors to a project.
Of course students should lead the work & writing of their honors thesis, but there's a difference between leading & doing it alone. We should teach science as it is practiced.
Nicola Romanò
boosted

Nicola Romanò
boosted

There is people out there thinking that computational biologists spend less time on scientific projects (not true) and therefore deserve less credit or even no authorship in papers, compared to wet lab people.
They clearly have never seen all the years and work that takes to gain the knowledge to do it. Just like they clearly do not value such a knowledge on lab work, since they only care about how many hours someone spend doing something.
Just reading this very interesting paper on how many #replicates are needed for appropriate analysis of bulk #RNAseq data and comparing tools for DE gene expression.
#bioinformatics #article #goodread
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC4878611/
From the abstract
With three biological replicates, nine of the 11 tools evaluated
found only 20%–40% of the significantly differentially expressed (SDE) genes identified with the full set of 42 clean replicates.
This rises to >85% for the subset of SDE genes changing in expression by more than fourfold. To achieve >85% for all SDE genes regardless of fold change requires more than 20 biological replicates.
Nicola Romanò
boosted

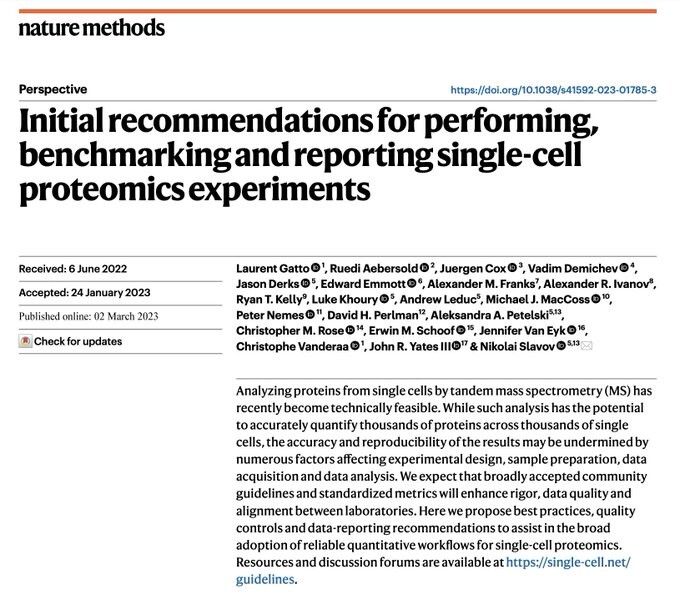
Big thanks to all who contributed to these initial guidelines, including the helpful reviewers and editors!
Nicola Romanò
boosted

 🇳🇱
Nicola Romanò
boosted

‘According to the Retraction Watch database, the 200 authors with the most retractions account for over a quarter of all 19,000 retractions. Many of the most prolific fraudsters are senior scientists at big universities or hospitals.’
https://web.archive.org/web/20230222193709/https://www.economist.com/science-and-technology/2023/02/22/there-is-a-worrying-amount-of-fraud-in-medical-research
#fraud #science #academia
Nicola Romanò
boosted

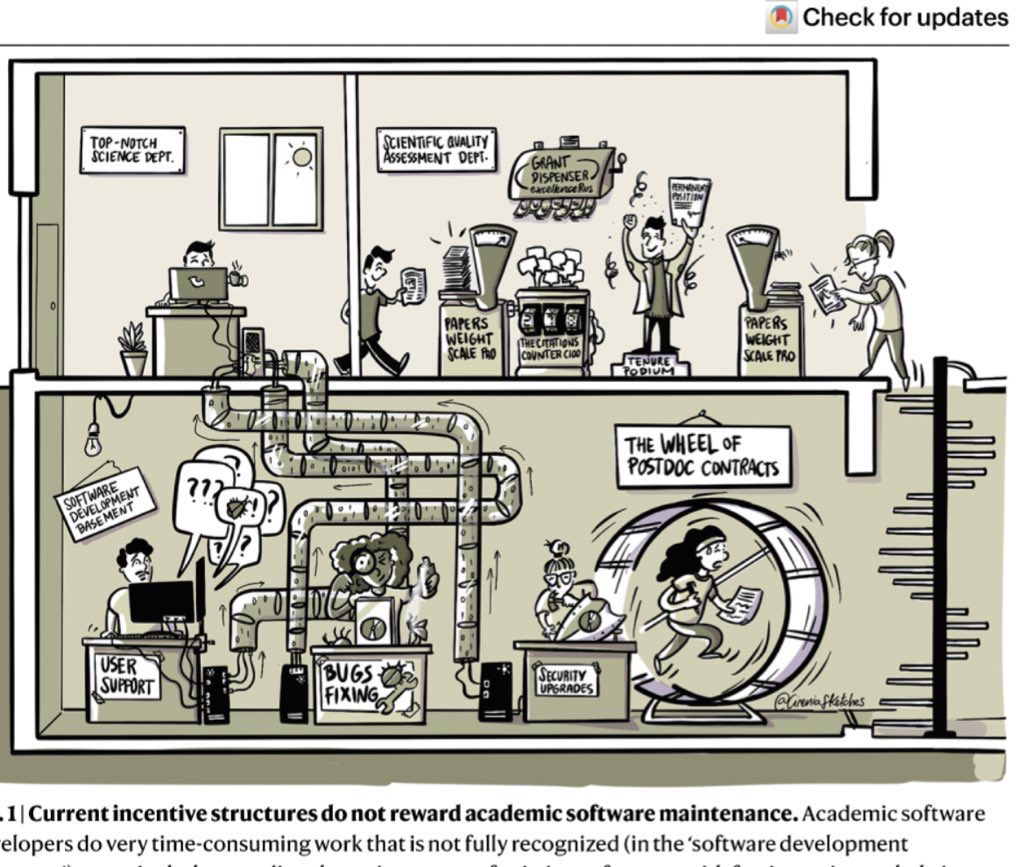
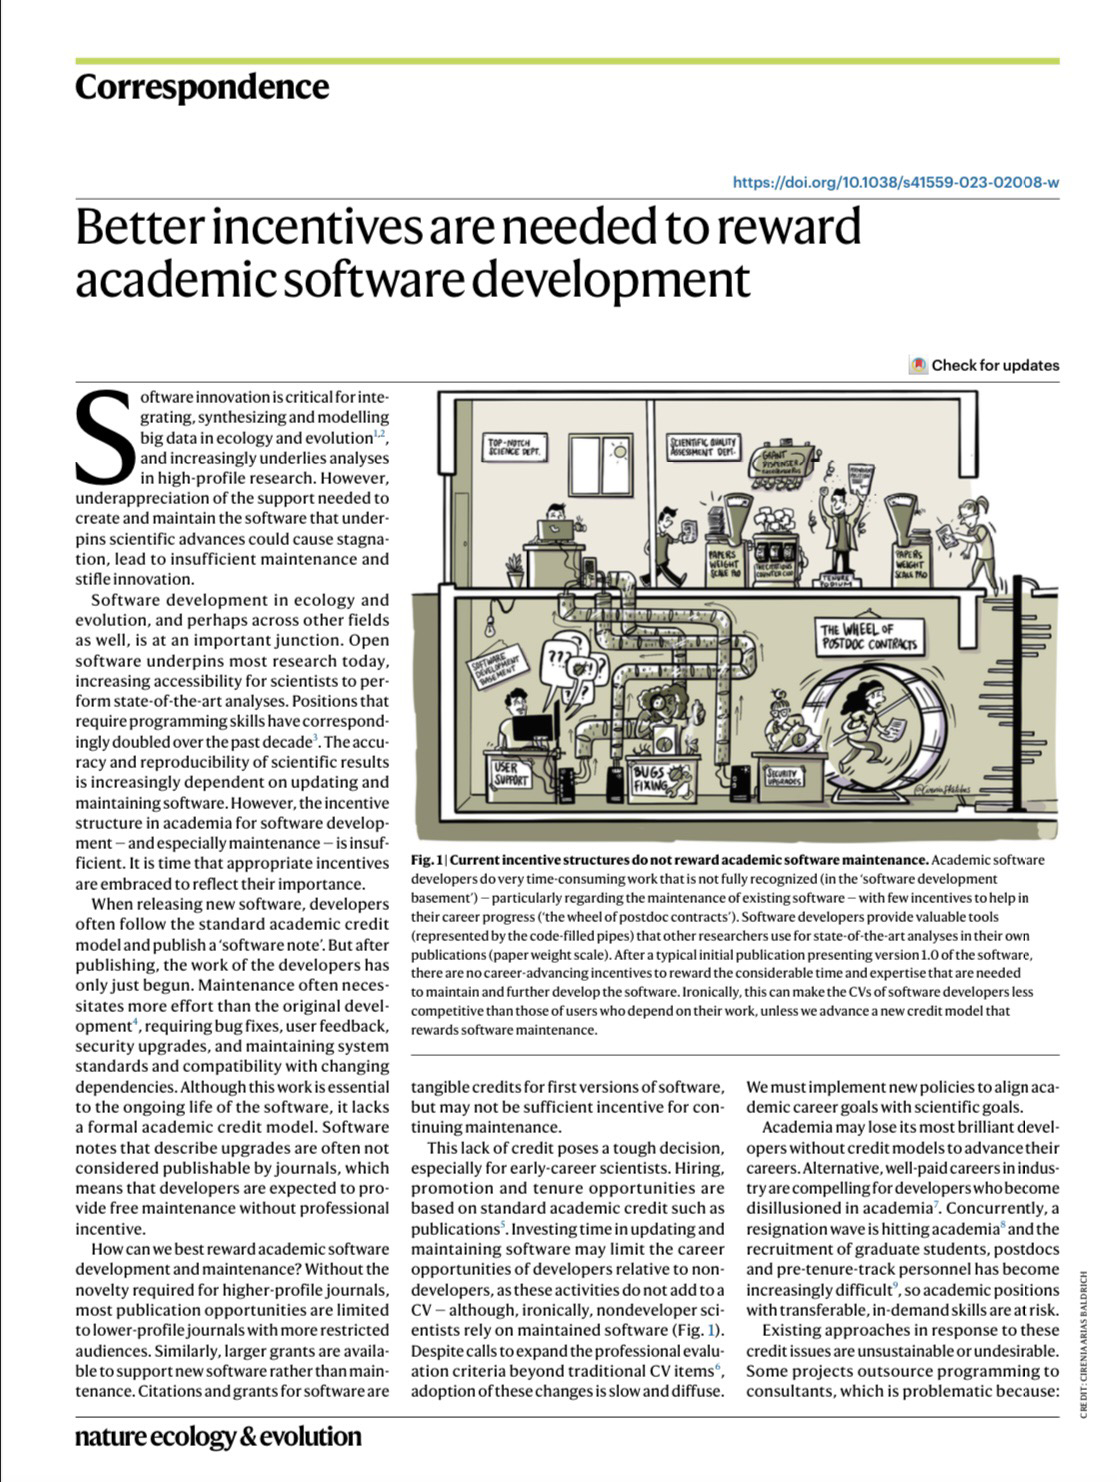
Check out our new commentary piece in @NatureEcoEvo - Better incentives are needed to reward academic software development rdcu.be/c6uMN software is critical for synthesizing & modeling big data in ecology and evolution … but current incentive structures are lacking
Nicola Romanò
boosted

Ok, so there is much discussion about the alt text on pictures. My mom is legally blind. As she has gotten older her sight is almost gone. She LIVES on the computer and to say she gets excited when special attention is paid for the blind is a great understatement. Please use alt text and describe the pictures you post. Describe it as if you had your eyes closed and the only link to the outside world is what a kind soul took an extra 5 minutes to type. Come on, do it, make someone’s day.#AltText
Nicola Romanò
boosted

If you see a bank account for donations to help cyclone victims, take the time to verify the account from an official published source.
For example: the recipient organisation's website.
Best not to just send money to an account repeated by social media users.
Nicola Romanò
boosted

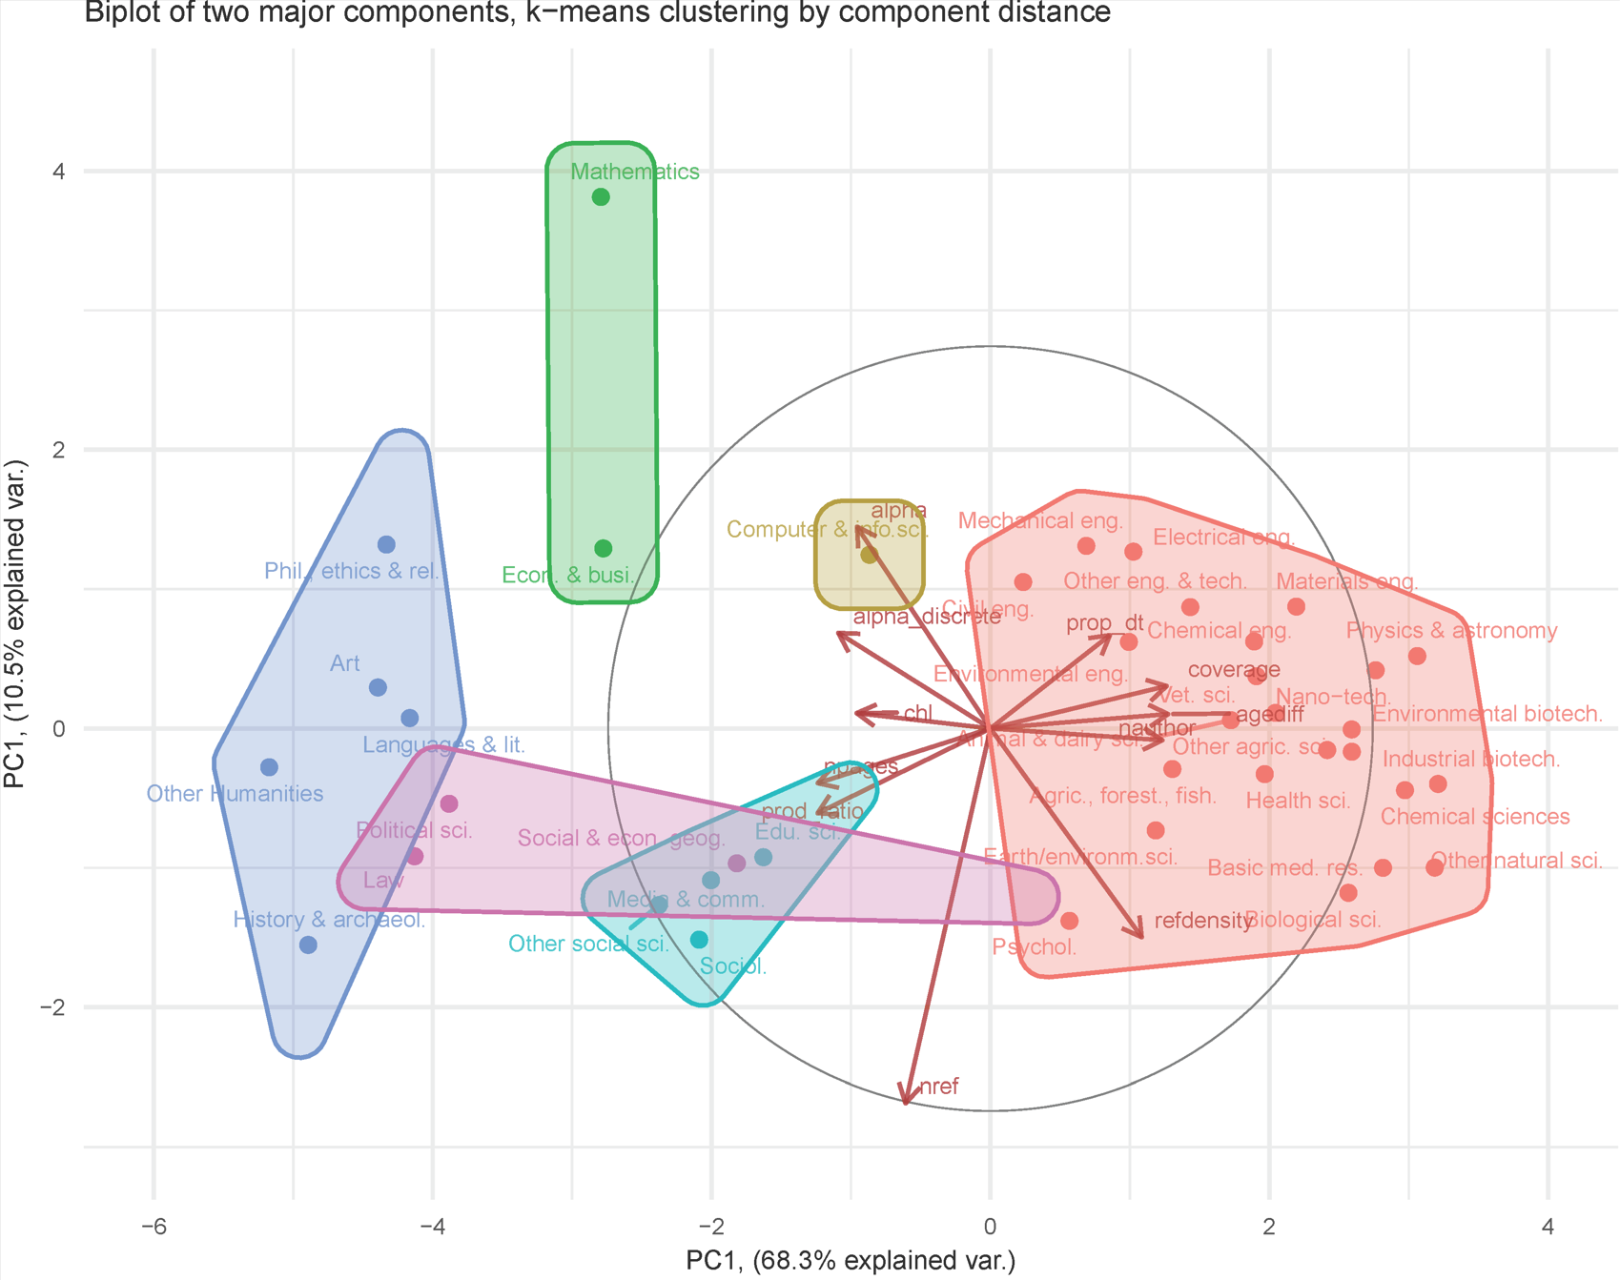
How are different scientific fields related, from a bibliometric point of view? Who writes longer papers? Uses more references? More recent references? In which fields does author position matter? Data for 20 years, all of Web of Science here:
https://doi.org/10.1162/qss_a_00246
Underlying, de-identified data can be found here: https://doi.org/10.5281/zenodo.7573523
Nicola Romanò
boosted

Nature news is really shooting itself in the foot - whenever I save an article and only get to reading it >14 days later, it's paywalled 🧱
Once again: Reliable information gets paywalled where misinformation is available for free.
Nicola Romanò
boosted

Okay, it's been a while since I last did this, and I haven't done it on mastodon yet, so I'm going to take a deep dive into p-values for another automated GWAS. Specifically, this one, relating to "Eosinophil percentage":
https://twitter.com/SbotGwa/status/1622218396661071874
I'm interested in this particular set of results because the p-values are impossibly large, with dozens of impossibly-large p-value peaks throughout the genome.
Also, the heritability of 0.22 is within the realm of possibility for finding true links.
Nicola Romanò
boosted




@ct_bergstrom Not sure what's this rant about. Nobody ever said decoder models are perfect or will have an actual understanding of the world. (Ok, maybe except for that one Google guy) OpenAI released a beta product which is incredibly helpful if used correctly but people like you just focus on its mistakes. It's like hating on cars because they can't take the stairs.
Senior lecturer at ZJE and Edinburgh university.
I teach #imageanalysis & #dataanalysis with #RStats & #python. I study #heterogeneity in #pituitary (and other) cells.
Joined Oct 2022
