This visual deep dive into one of the largest AI language datasets is nonstop fascinating, jaw-dropping, and troubling, and anyone who is remotely interested in how LLMs really work, their biases, or intellectual property should read it. https://www.washingtonpost.com/technology/interactive/2023/ai-chatbot-learning/
"Content without consent" is a concern that I could see catching on as more people gradually realize the content they've published and posted over the years is being secretly used to train for-profit AI models. https://www.washingtonpost.com/technology/interactive/2023/ai-chatbot-learning/
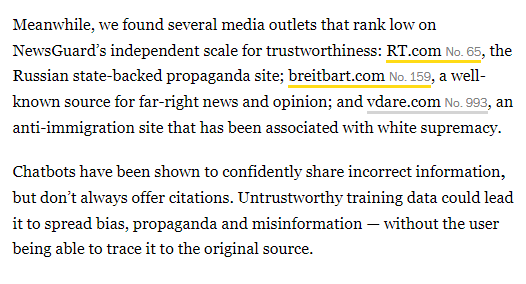
If your AI chatbot is spouting some disturbing views, it could be because the websites that contributed the most language tokens to its training dataset include the likes of RT, Breitbart and VDare.
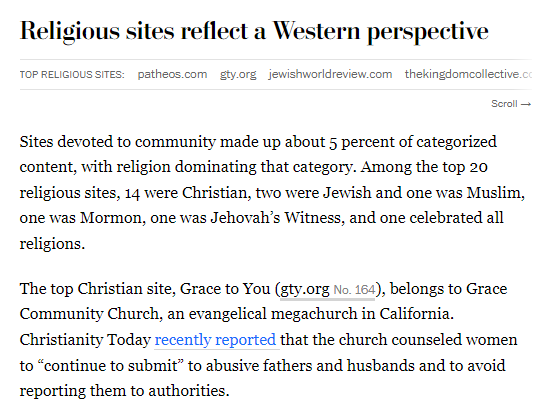
If you're asking an AI chatbot questions about religion, you probably shouldn't expect the perspectives of non-Christian faiths to be well-represented, based on this analysis of what sites make up Google's massive C4 dataset. https://www.washingtonpost.com/technology/interactive/2023/ai-chatbot-learning/